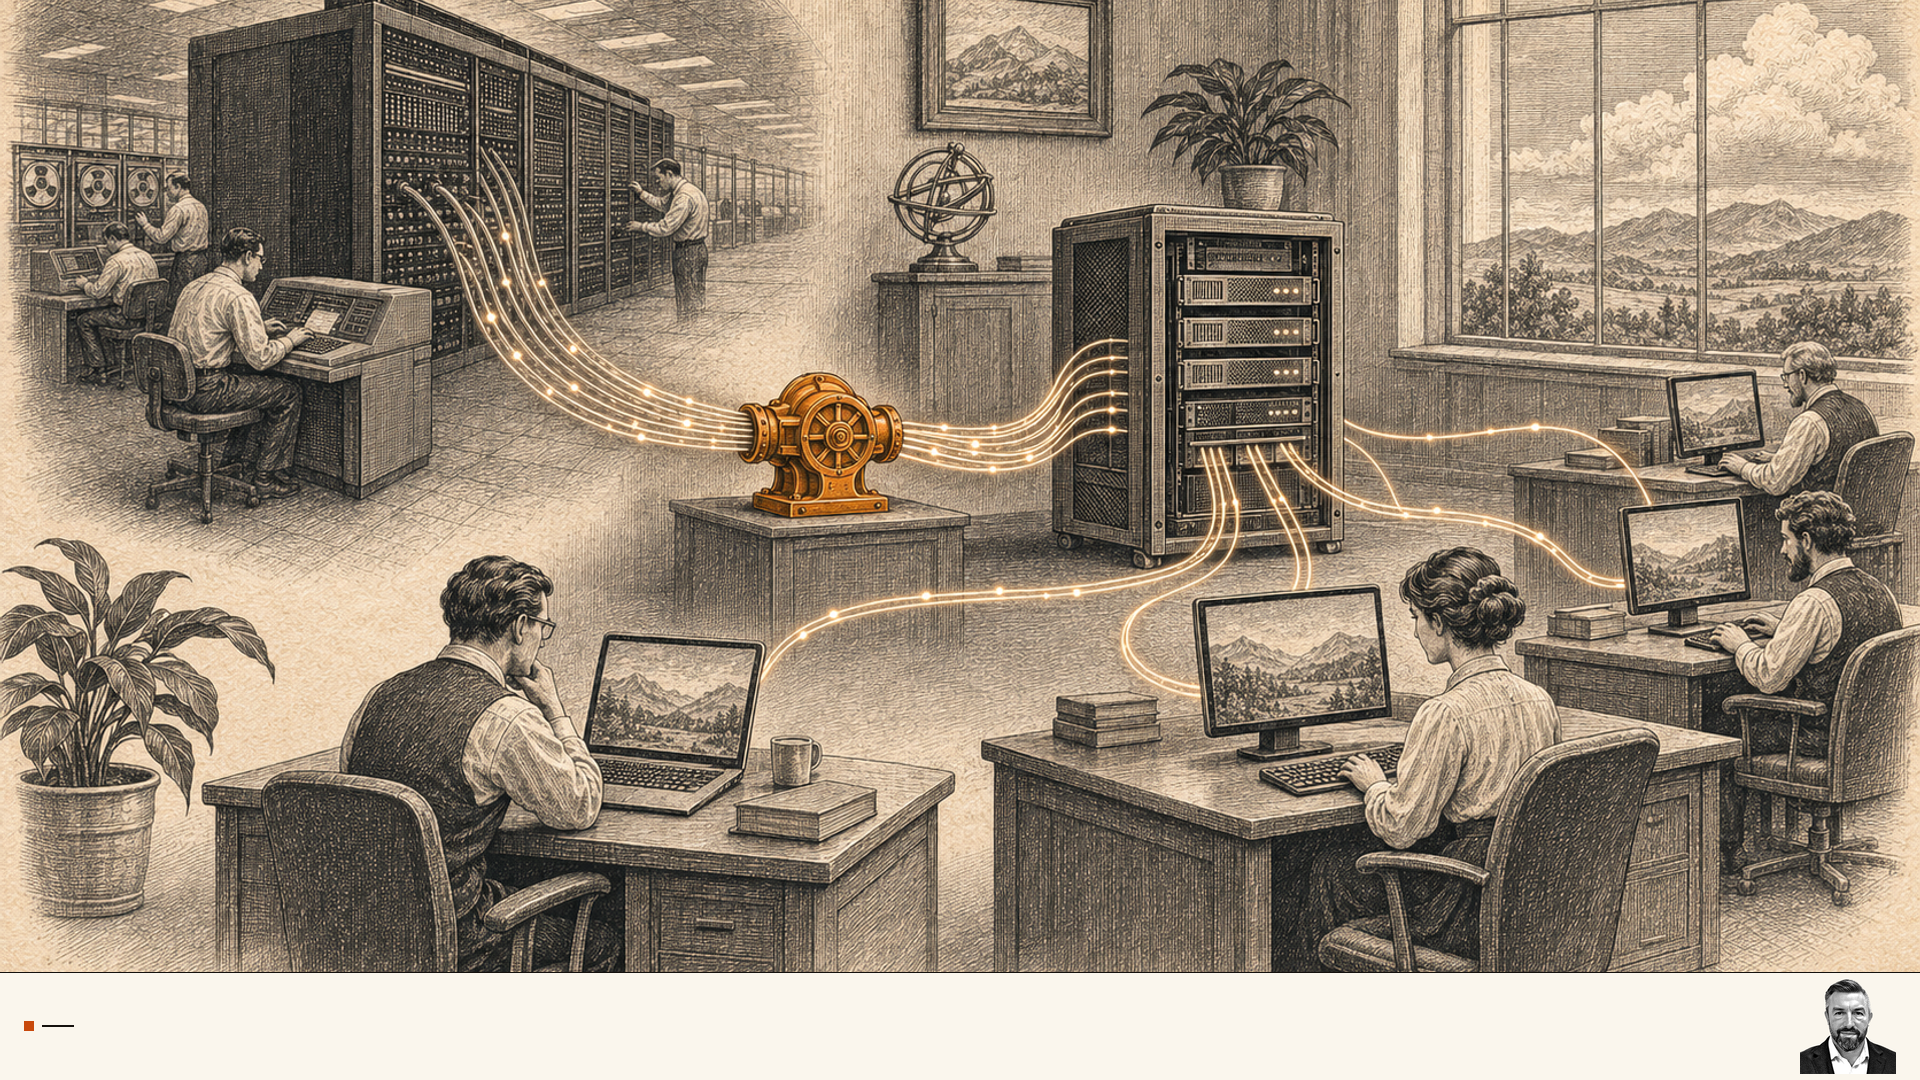
A November 2026 follow-up to The Mainframe Era of AI Is Ending.
Anthropic just told investors that open models could take some of its business.
In its October S-1, a public stock offering filing that identifies risks to the business, Anthropic warns that open models could win particular use cases and put pressure on its prices. That raises a question for a company building some of the most capable models in the world: What happens when your customers don’t need your most capable model for everything?
In June, I wrote that the mainframe era of AI is ending. I argued that more inference would move closer to the people and businesses using it, with local models handling suitable work and frontier models available when the task justified them. I also predicted a routing layer would decide where that work belonged.
Five months later, Anthropic is warning investors about the competitive pressure that could result if customers move some work to open models. Revolut is describing an open-model-first coding setup and a way to route work by capability. Neither settles how the market will develop. But both point toward the shift I described, and I’m going to take a small victory lap.
Anthropic’s filing makes the economic side of that argument clearer. A smaller system doesn’t have to outperform the mainframe at its hardest jobs. It just has to do enough useful work at a price and level of convenience that make it worth choosing.
The Workload Has a Vote
Think about an application that processes customer support requests. It needs to identify the language, classify the topic, retrieve the customer’s account information, draft a response, and decide when to involve a person.
Those are not all the same problem. Language detection may be handled by a small classifier. Account lookup should follow deterministic authorization and retrieval rules. A straightforward response might be drafted by a smaller model, while an ambiguous dispute or a sensitive exception gets escalated to a more capable model and a human reviewer.
You can send the entire workflow to your most expensive model. You might even get a good result. But you have paid for that capability at every step, including the ones that never needed it.
The question isn’t whether a smaller model can solve every problem your strongest model can solve. The question is whether it can solve this problem reliably enough, at a price and operating cost that make sense. If it can’t, route the work elsewhere. If it can, the premium model no longer has an automatic place in that transaction.
This applies to closed models at different price points, too. You don’t need to run an open model to decide that a less expensive hosted model is sufficient. But open weights add another option: you can deploy an available model on infrastructure you control, subject to its license and the practical costs of running it.
That’s the argument I made in the “Most Work Does Not Need the Biggest Model” section: a local model doesn’t have to beat the frontier. It has to be good enough for the work in front of it. When enough work meets that standard, the economics of the entire stack start to change.
Revolut Is Already Making the Trade
Revolut offers a concrete example of that decision. At AI Engineer NYC in October 2026, David Abitbol described serving a self-hosted GLM coding model to roughly 2,000 engineers using a fleet of 56 NVIDIA B200 GPUs. His team made open models the priority while retaining frontier services for exceptions. This is not a small model running on a spare laptop. It is an organization operating substantial infrastructure to serve its own workload.
Abitbol reported a blended token cost of $0.30 per million and said the self-hosting invoice was one-tenth of what Revolut had spent with Anthropic and OpenAI. That’s a striking company-reported comparison, but the presentation does not establish matched usage, comparable billing periods, or the full engineering cost of operating the service. It is not evidence that every organization can reduce its total AI costs by 90%.
The architectural decision matters as much as the invoice. Abitbol proposed keeping the main coding task with GLM and routing image recognition to a vision-capable model, while frontier tools remain available. That is the kind of hybrid routing I described in June: match the work to the model that can handle it, and keep the cloud available for work that needs something else.
Revolut’s infrastructure fits the scale of its work. Serving roughly 2,000 engineers calls for a GPU fleet, just as a home or small office might eventually use an appliance sized for its own needs. The principle is the same: run suitable work on infrastructure you control and keep other models available when the task calls for them.
Revolut also shows what makes the economics possible. The team tuned how it served the model on its GPU fleet. On the same 56 GPUs, a presentation slide showed the wait for the first token falling from 14.26 seconds during migration to 1.68 seconds in a stable configuration.
That tuning takes expertise, capital, and investment in people. It also shows why inference hardware and operating capability matter as much to this transition as the model download.
What Anthropic Actually Said
Anthropic’s filing says open-weight and open-source models may capture portions of the market for certain use cases and create pricing pressure. It also describes a broader competitive field: companies selling models at or below the frontier are pursuing enterprise work that values cost efficiency. Anthropic’s response is not to concede that space to open-weight models. Elsewhere in the filing, it argues that its frontier models are effective and efficient across both routine tasks and customers’ most demanding work.
That is the fight. The frontier provider wants its most capable infrastructure to be an attractive place to run the whole workload. The customer wants the right result at an acceptable cost, with the control and reliability the business requires. Those interests can align. They don’t always require the same model.
According to the transcript of All-In episode 295, David Friedberg described his organization using an open-source cluster and suggested that model providers could price easier tasks differently from premium work. That’s a participant’s observation and prediction, not a measurement of where enterprise workloads have moved. His point is still useful: intelligence can be sold at different levels because the work demands different levels.
The same discussion contains a serious counterargument. David Sacks pointed to Anthropic’s reported efficiency and margins as a reason to doubt that open competition is inevitably driving frontier providers toward commoditization. If a frontier lab can make its models much cheaper to run, reduce prices, and keep improving quality, it can compete for those ordinary workloads as well.
He’s right to raise it. A capable hosted service with excellent reliability, support, and falling prices can be a better choice than a model your team has to operate itself. The end of the mainframe era doesn’t require the end of the mainframe. It means the central machine stops being the only sensible default.
Are We Before the Clone Explosion?
The PC analogy is useful here, as long as we don’t force the history to fit the prediction.
Personal computers existed before IBM introduced its PC in 1981. IBM’s machine helped establish a platform for business computing, and compatible machines followed. The Computer History Museum describes how a growing population of IBM-compatible computers gave software developers an incentive to target that platform, while competing machines eroded IBM’s lead in the PC market.
The clones competed with IBM’s PC, not directly with a mainframe. Mainframes didn’t disappear, and they continued doing work that smaller machines weren’t equipped to replace. What changed was the range of work that could be done on machines that organizations and individuals could buy and use for themselves.
I think open-weight AI may be approaching a comparable stage. We have models people can run themselves, a growing set of tools around them, and businesses interested in control over their data and workloads. What we don’t yet know is how quickly the hardware and operating economics will make that choice practical for a much wider range of organizations.
For local AI, silicon is a real candidate for the constraint. A model can be available to download and still require more memory, bandwidth, power, or capital than a buyer can justify. Hardware supply and price affect how quickly the option reaches beyond enthusiasts and well-funded companies.
But silicon isn’t the whole story. A business also needs software, integration, maintenance, security, and people who can operate the system. Revolut didn’t just deploy GLM and walk away. Its team tuned the serving configuration and managed the GPU fleet to make the system work for its engineers. Access to hardware creates the opportunity; the organization still has to make effective use of it.
The Stack That Could Emerge
The more interesting future isn’t one machine replacing another. It’s a system that chooses where each piece of work belongs:
- Deterministic code handles rules, validation, and operations whose correct behavior you can specify directly.
- A small classifier or router identifies the task and selects an appropriate path.
- A local or open-weight model handles work it can perform to the required standard.
- A frontier model takes the difficult cases that justify its additional capability and cost.
- A person makes or reviews decisions where the consequences and uncertainty require human judgment.
That is a possible architecture, not a mandatory chain. A router can be wrong. A small model can produce a plausible answer it shouldn’t have produced. An escalation can fail to trigger. Some requests should go directly to a person or a frontier model, and some should never leave deterministic code.
The team owns those decisions. Build a representative set of real tasks, define what success and failure look like, and test each route. Recheck the boundaries when the model, hardware, or workload changes.
This is also why cheaper inference doesn’t make engineering judgment less valuable. As more execution becomes affordable, architecture, orchestration, verification, and control determine whether the lower-cost path produces a result the business can trust. I made the related case in Cheaper Code Exposes the Verification Constraint: producing more output does not remove the need to establish that the output is fit for purpose.
Don’t Compare Token Prices and Stop
An open model may have no per-token API charge, but running it is not free. Someone buys or rents the hardware, pays for power and capacity, installs updates, manages access, monitors failures, and maintains the integration. A lightly used machine can be more expensive than an API. A heavily used one can change the calculation.
The same goes for quality. A cheaper answer that creates more rework, misses important cases, or escalates too late can cost more than a premium model. A hosted model can also be the more practical choice when demand is uneven or the business doesn’t want to operate inference infrastructure.
Run the comparison on the workload you actually have. Include capital and operating costs, utilization, response time, privacy requirements, error costs, and the cost of verification. Then decide which work belongs where.
The Default Is What Changes
Frontier labs will continue to build systems that smaller models cannot match on the hardest tasks. There is a real market for that capability. There will also be organizations that prefer to buy a managed service instead of owning another piece of infrastructure.
But a market doesn’t need one winner for the economics to change. If open and mid-tier models take enough routine work, the frontier model becomes an escalation path for more systems instead of the starting point for every request. That’s the shift I predicted in June. Anthropic has now identified a piece of it as a business risk, and Revolut has shown what an open-model-first approach can look like at enterprise scale.
The timing depends on hardware, software, cost, and whether the smaller systems actually meet the standard each workload requires. The direction is the part I keep coming back to. Computing moved outward when more people could afford machines that were good enough for their work.
AI doesn’t need a better mainframe in every office. For a growing share of the work, it needs an affordable machine that can just do the job.
Receipts
- Anthropic’s competition and compute risks: Anthropic S-1, filed October 26, 2026, especially printed pages 41–42. The filing describes competitive scenarios and risks, not measured future market shares.
- Revolut’s self-hosted deployment: David Abitbol’s AI Engineer NYC presentation, October 2026, and The Register’s coverage. The cost and latency figures are Revolut’s reported experience. The presentation does not specify matched usage and billing periods or complete operating costs; image routing was presented as an approach.
- Podcast discussion: All-In episode 295, timestamped transcript, October 30, 2026. The discussion around 8:43–10:23 and 15:54 informs the competing interpretations above. Speaker attribution follows the automated transcript.
- PC history: The IBM PC and the Computer History Museum’s Send in the Clones. These describe the IBM PC and compatible-computer ecosystem. The comparison to AI is my inference.
- Anthropic’s open-weights position: Our position on open-weights models, July 27, 2026. Anthropic’s discussion of powerful chips is principally about training and national security; it does not establish local inference economics.